When Good Is Good Enough: The Eval Nobody Runs
A relative lost his job to an agent, so I built him one. Choosing which model should interview him cost a day, $22, and one reversal I did not enjoy. The model was never the problem. Six other things were, and finding them is the eval nobody runs.

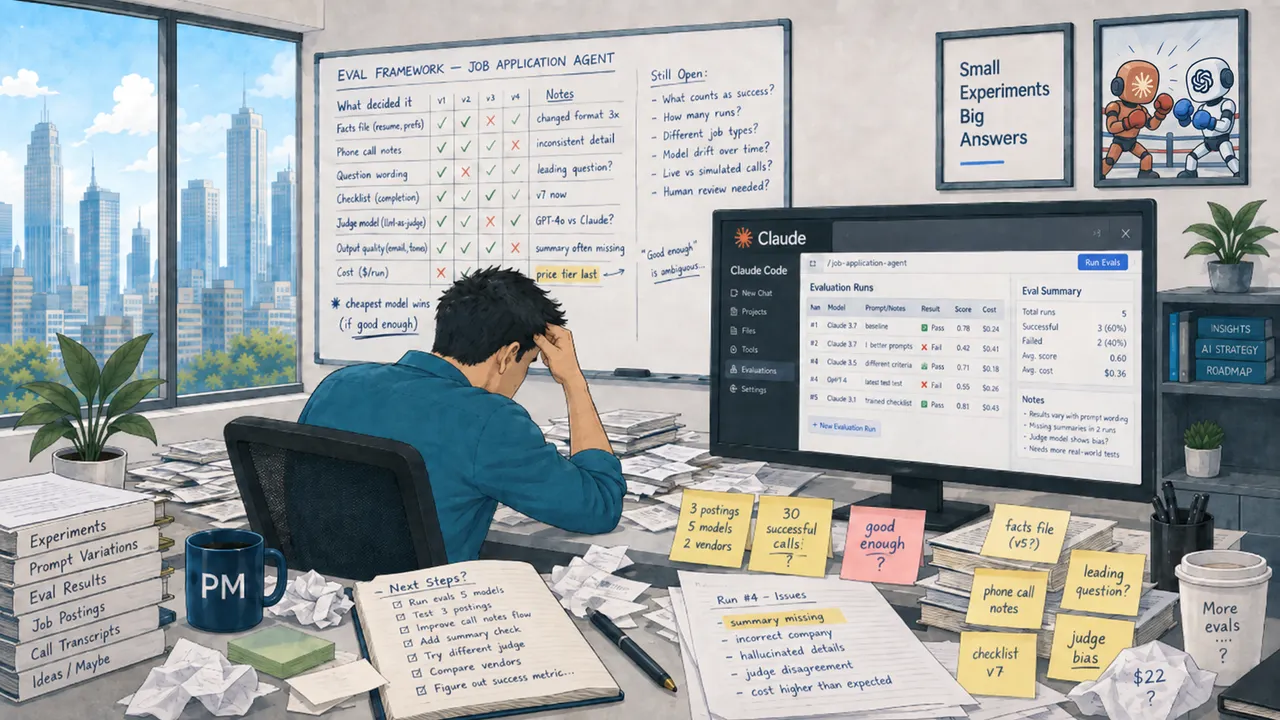
A close family member lost his job this summer, in part to an agent. I am building him one back: an agent that helps him find his next role. Last week I was faced with an interesting question: which AI model should run one step of that system? Not the best model. The right one for that step. The answer took a day, about twenty-two dollars in API calls, eleven written decisions, and one reversal I did not enjoy. What I learned along the way is not about models. It is about why almost nobody does this work properly, even though nothing in it is hard or expensive.
The step
The agent reads a job posting, compares it with a file of verified facts about his career, finds the gaps, and asks him three to five questions before it drafts anything. That interview step is the whole point of the system. A resume assembled from verified facts is only as good as the facts, and the questions are how the facts get better. The step has one job: find what the posting wants that his record does not yet show, and ask about it without putting words in his mouth.
That last part matters more than it sounds. A question like "For the governed AI tooling you built, how many customers used it?" is not a question. It is a claim about his past that he never made, dressed up with a question mark. If he answers it, his resume now says he built governed AI tooling. The step is worth having only if it never does that.
So the test was simple to state. Three real postings, one file of facts, one model at a time, and four checks: did it find the real gap, did it ask for a number, did it ask for a customer or example, and did it avoid leading him.
What the first run said
Three models from one vendor, three price tiers, the same three postings. All three failed the same way on the same two postings. None found the gap that mattered. The most expensive model did not find it either. It did, however, invent the most history for him.
So far I had spent top dollar to compare three flavours of the same hallucination. The obvious reading was "the models are not good enough." The correct reading took another hour: the models never saw the information they needed. A program upstream of them had extracted the job's requirements as exact quotes from the posting, and the requirement that mattered was never written in the posting. It was implied by what the company is. Every model was starved the same way, so every model failed the same way, and the price tag made no difference. You cannot buy your way out of a missing input.
What the second run said
We fixed the input and ran again, this time with a fourth model from another vendor and twelve synthetic test cases written by someone else. I will admit I was also watching, with some interest, to see whether Anthropic would beat OpenAI or the other way round. The models had no idea they were in a race, and nobody won. Now the failures moved. The expensive model still put words in his mouth. The mid-priced model did it less. The other vendor's model did not do it at all. And a graded checklist I had written for the step turned out to be wrong: it marked a fact as "thin" whenever a date or a number was missing, so a model that followed my rule to the letter failed a case that a model ignoring my rule passed.
That is the pattern for the rest of the day, and it is the point of this article. Each run changed one thing and found that the thing we thought we were measuring was not the thing that moved.
Six things moved, and none of them was "the model"
Here is the honest list of what varied over the day, and what each one actually did.
The model family and its price tier changed how often the model invented his past. It did not change whether the model found the gap.
The prompt rules changed the failure count from six to one on the synthetic cases, and they took three rounds because the same fault kept appearing in a new grammatical form. Two rules caught "the X you built." Neither caught "For the X you built, how many..." The fourth rule is still open. I now know more about the grammar of a leading question than any product manager should.
The context, meaning the facts file and the notes attached to a posting, was the only thing that ever produced a found gap. When he gave me three facts he had never written down, a menu question about data platforms became a real question about his data platform. When the notes from a screening call never reached the model, every model asked about the wrong thing.
Thinking mode, the setting that lets a local model reason before it answers, made the local model worse on this task. Five minutes of reasoning, zero questions.
Memory and quantisation decided whether a model could be tested at all. A 72-billion-parameter model at eight bits paged to disk and produced half a token a second; I could have typed the questions faster, and mine would have been better. At four bits it ran, slowly, and asked the kind of questions you get from a recruiter who has not read the resume.
The judge's family mattered as much as the candidate's. When I had a model from the same vendor grade the output, it passed questions that a model from another vendor failed, and the other vendor's model was right. It quoted the exact words. Nothing sharpens a grader like marking a competitor's homework.
And one thing I had not thought of as a variable at all: the expected answer. Two days into the work he added the missing facts to his file. The reference answer for one posting, written before those facts existed, was now wrong. A model that treated the requirement as covered was marked as having missed it. The evidence had moved and the expectation had not. I had built a test that penalised the model for knowing more than the test did.
Why nobody does this
Nothing above needed a data centre. A laptop, two API keys, three postings and one man's file of facts. Twenty-two dollars. Yet in twenty years of building software I have rarely seen this done, and I think there are four reasons, none of them technical.
Nobody owns the bar. Someone has to write the pass condition before the run and hold to it after, and that person has to be willing to move their own preference when the evidence says so. I moved the default away from the model I like twice in one day. Most teams have a vendor relationship instead of a bar.
The expensive part is invisible. Tokens have a price on an invoice. The three real postings with verified facts and one set of notes from a screening call took weeks to assemble, and the twelve synthetic cases took a day. Nobody budgets for the person who writes the expected answers, and without them the runs measure nothing.
The write-up is the fragile part. Every expensive run I did this week produced raw output first and a readable table only after someone rebuilt it by hand. One run I believed had failed had in fact completed; only its summary was missing. Thirty model calls, all successful, sat in a folder looking exactly like a failure, which is how most successful experiments end. In a real project that is the moment the work gets cancelled. The fix is embarrassingly small: write the empty table before the first call, and let each call fill its cell. Clinical trials have done this for decades. They call it a case report form.
And the answer is usually unwelcome. Mine was that the top tier of my preferred vendor was not needed, the cheapest passing tier was not clean, and the honest default was the middle tier from the other vendor. Nobody in a room wants that sentence, least of all the person who had been rooting for the home team. That is a fair test of whether an eval was real.
What the physician in me recognised
I trained as a physician before I built products. What I did this week has a name in medicine: differential diagnosis. One presenting symptom, several plausible causes moving at once, and the only way through is to change one thing at a time, write down what you expect before you look, and accept that the answer is a probability you will revise, not a verdict you will defend.
People who spent twenty years building deterministic systems find this uncomfortable, and I understand why. A function returns the same output for the same input, and when it does not, that is a bug. A model returns a distribution, and the distribution is the product. The engineers' instinct is to add a rule until the output is stable. The clinician's instinct is to ask what the variance is telling you. Both instincts were needed this week. The rules caught real faults. The variance told me where the fault was not.
Software engineers do have one instrument physicians never had. You can freeze the patient. Every run carried a hash of its input, its prompt, its rules and its configuration, so any result can be reproduced and any two runs can be compared. That is the discipline that makes the clinical method safe to use on software: the ambiguity lives in the model, never in the experiment.
A disclaimer that is also the method
Every model ran once per posting until the last day. A single run proves that a failure can happen; it says nothing about how often. When I finally ran five draws per posting, the question sets agreed with each other about a quarter of the time, and the cause was not the model. It was the program upstream, which rewrote the list of requirements in different words on every call. Freezing that list doubled the agreement. Only then was the variance a property of the model.
So the decisions I made during the week were made on early signs, and they were written down with the condition under which they would be revisited. That is what a shortcut looks like when it is a protocol rather than a habit.
Good enough is a decision, not a score
The model I chose is not the best model available. It is the cheapest one that cleared a bar I wrote before I ran it, on a task I defined narrowly, judged by a model from another family and by me. When the bar moves, the decision moves, and the record says why. That is all "good enough" has ever meant, in medicine or anywhere else. The score is the evidence. The decision is the work. Nobody skips the score because it is expensive. They skip the decision because someone has to own it.
Part of the Product Management series: how AI is changing what product managers actually do.


