The Model That Cannot Write a Sentence
Three weeks ago a logistic regression beat eight LLMs at reading job postings. I gave it a rematch against a model built for tables. TabPFN-3.5 beat the lion, beat GPT-6 Astra and Claude Fable on the same postings, ran in 12 seconds per thousand, cost nothing, and fits in 876 MB.

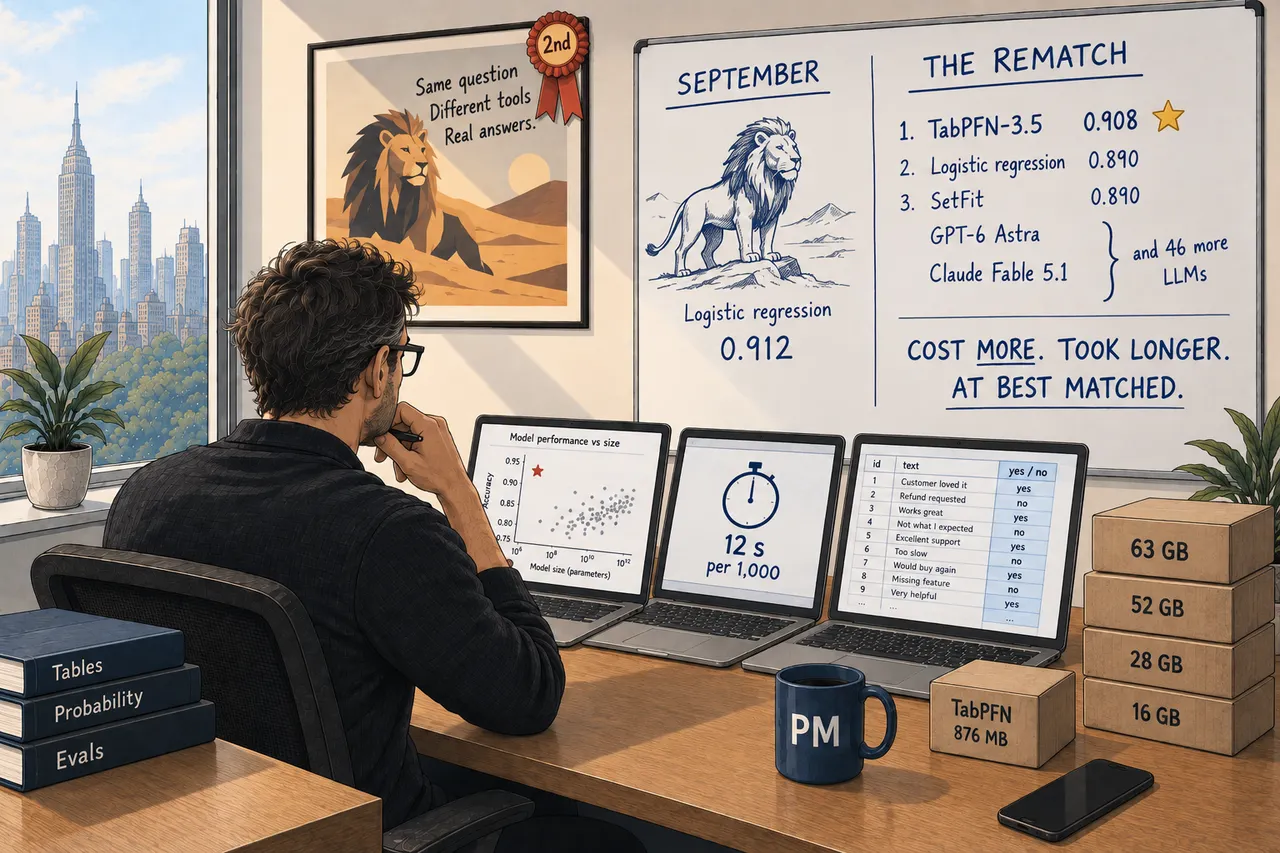
Three weeks ago I wrote that a logistic regression had beaten eight language models at reading job postings, and that the real finding was not the winner but the speed: an architecture decision that used to cost a quarter now cost a weekend. The lion in that story was a formula from a statistics textbook, and I was content to leave it there.
Then SAP's CTO posted his team's NeurIPS papers list and I noticed the thing I had not tested. Every model in my table either writes sentences for a living or was built by me from parts. I had never tried the one category built for exactly this problem: a model that reads a table of labeled rows and returns a probability for the next row, and does nothing else. So I gave the lion a rematch.
What I ran
The agent is the same one. It reads job postings for a family member who lost his role to an agent, decides which deserve his eyes, and matches the survivors against what he has actually done. Since September the labeled set has grown from 300 postings to 2,458, with 626 marked yes, across 398 employers. That is one person's taste, not an objective label, which makes it a harder problem than fraud detection and a more honest one than a benchmark.
The model is Prior Labs TabPFN-3.5, the open-weight base version, downloaded to my laptop and run on Apple silicon with nothing sent anywhere. No Thinking mode, no Plus, no API. I handed it the seven features my hand-built ranker already used, plus the raw posting title and description as text columns, and did no feature engineering at all. It fits in about a second. The weights file is 876 megabytes.
The test holds every posting from a given employer out together, so the model is never judged on a company it has seen, repeated across five folds and five seeds. Roles at one employer are correlated; a random split flatters everything. I ran the random split and a newest-fifth holdout too, but the employer-held-out number is the one I trust.
The rematch
TabPFN scored first, with 0.908 AUC. The logistic regression that won in September came second at 0.890, SetFit tied it, the gradient-boosted ranker I had been running in production trailed at 0.849, and BM25 at 0.830. The gap to the logistic head is small and the interval around it does not include zero. On the ten postings it ranks highest, which is the only number my family member actually experiences, it got nineteen of twenty right against the logistic head's eighteen and a half. On the newest fifth of postings, never seen, it went ten for ten.
So the lion lost, narrowly and clearly, to a model that never saw a job posting before it saw mine, was never tuned, and was never told what an "engineering manager" role is.
| Method | Gap to TabPFN (AUC) | Time per 1,000 | Cost per 1,000 |
|---|---|---|---|
| TabPFN-3.5, local, untuned | first, 0.908 | 12 s | $0 |
| Logistic regression | -0.017, clearly | 0.4 s | $0 |
| SetFit | -0.018, clearly | 132 s | $0 |
| GPT-6 Astra | -0.045, clearly | ~12 min | $4.20 |
| Claude Fable 5.1 | -0.060, clearly | ~15 min | $6.30 |
| BM25 (1994) | -0.078, clearly | 0.1 s | $0 |
| Jev, local replica | -0.085, clearly | 74 s | $0 |
The more interesting rows are the ones that did not help. Fine-tuning TabPFN on my data did nothing. Metric tuning for the class imbalance moved the label-level scores and left the ranking alone. Adding my own embeddings to its input did not beat handing it the raw text. Every clever move I made on top of the model cost accuracy or bought nothing. The best configuration was the laziest one: raw title, raw description, the seven numbers, done.
Against the models that write
That was the rematch against the classics. The comparison that made me sit up is the one against the language models, because I had already paid for it. Over six weeks the pipeline had stored the judgments of 46 model configurations on these same postings: local models from 26 to 120 billion parameters, hosted models from the cheapest tier to the newest frontier releases from both labs, under production rubrics, triage prompts and editor briefs. None of those scores were fitted to my labels; they existed before the labels did. So I could put TabPFN on exactly the postings each model had judged and compare like with like. The full table is at the end.
It was ahead of every one of them. The two newest frontier models got the full treatment on 958 postings each, and both finished clearly behind, with companies held out. The bigger and pricier of the two scored lower, but the intervals overlap, so the honest reading is not that more power hurt; it is that more power did not help, and cost more and took longer. The only row TabPFN could not separate from was one Sonnet 5 run, and that was a tie, not a loss. The best language models in the world, asked to read a posting and say yes or no, landed below where my logistic regression had been in September.
One split deserves its own sentence. When TabPFN learns only from older postings and is judged on newer ones, Astra, Fable and the best local models catch up to a tie. The language models know things about the world that my labeled history does not, and on the newest postings that knowledge is worth about as much as my history. So the claim is not that TabPFN crushes the frontier. It is that the frontier, at its best, matched a model that ran a hundred times faster for nothing.
Because that is the second axis. TabPFN judges a thousand postings in twelve seconds on this laptop, thirty-eight on the CPU alone. The language models took between a few minutes and a full day per thousand, and the frontier models cost real money per batch. The smallest local language model in my cache is eighteen times the size of TabPFN's weights.
Cost more, took longer, at best matched. That sentence held for every model I had run, and I had run a lot of them.
The problem I thought was trivial
What surprised me most, after six weeks of this, is how hard it turned out to be to get good results on something I had filed under "trivial". Classification and matching are the oldest problems in software. Is this row a yes or a no; which of these candidates belongs with that one. I have followed healthcare AI for years and I know how much of medicine is exactly that: a differential diagnosis is a ranked match of findings to conditions, a prescription is a classification of a patient against a set of rules, a prognostic score is a probability from a table of labeled histories. The same shape runs through every industry. Which invoice needs a human, which lead is worth a call, which shipment will be late, which claim will be denied. They are tables with a label column, and they have been since before any of us were born.
Language models are extraordinary at prose, and I use them for it every day. But a language model classifies by writing an answer, which means it can be fluent, confident and wrong, and the better it writes, the more persuasive the wrong answer. In September the most expensive model invented the most history. A model that can only output a number has no prose to hide behind.
TabPFN is that model. It is not a language model; it is a transformer trained on millions of synthetic tables and never on a word of internet text. Show it labeled rows and it returns a calibrated probability for the unlabeled ones, in one pass, with no training step. The research version of this is known; its predecessor was in Nature last year, and SAP bought the lab that makes it in July. What is not known, judging by every architecture conversation I have been in this year, is that it exists at all. Product teams have learned that AI means a language model and reach for one at the first classification problem they meet, which is the first problem they meet.
What this means for a business
Three numbers from the table are the ones a product manager should carry out of this article, and none of them is the AUC.
Twelve seconds per thousand means the model fits inside the request. A score that takes a quarter of an hour per thousand rows is a nightly batch; a score that takes twelve seconds is a column in the application, refreshed every time the data changes, which is the difference between a dashboard and a decision
Zero dollars and no training step means the person who owns the decision can run the model. There is no feature pipeline to build, no fine-tuning job to schedule, no vendor to call. A product manager with the labeled rows and a laptop gets the answer before the architecture review is on the calendar, which is the whole argument of the previous article in this series.
And 876 megabytes means it runs where the data is. My postings never left the laptop. A hospital's records, a bank's transactions, a manufacturer's quality logs do not have to leave the building to be scored, and the model's answer is a probability with a threshold you set, not a paragraph you have to read.
What changed on Monday
I switched the production ranker. The agent now scores every posting that passes the gate with TabPFN, refit in context on the labeled rows each time, with a fingerprint on the model version and a rollback to the old ranker if the worker fails. The first full retrain and ranking of 6,385 postings took 76 seconds including loading the weights. Whether it was the right call will be decided by the yes rate on his daily picks over the next two weeks, and that number is already being collected.
Two caveats, because the previous article made a point of them. The headline is the best of several TabPFN configurations I tried, which flatters it a little. And the open weights are licensed for testing and evaluation, not production; this is a personal project on a laptop, and the commercial version is a different product with a different price.
What I keep coming back to is the table from September with one row added at the top, and what that row cost. Not a quarter. Not a weekend. A Friday evening, a download, and the willingness to test the category of model nobody in the room had heard of. The lion is a formula from a textbook. The thing that beat it is the formula’s descendant, and it ran on the laptop next to me.
The full table
Every language model that judged at least 200 of the labeled postings, one row per model at its best configuration, with the number of configurations tried alongside. Each row is scored on exactly the postings that model judged, companies held out, so the TabPFN column moves with the row. Gap is model minus TabPFN; negative means TabPFN was ahead, and the verdict says whether the 95 percent interval excludes zero. Time is wall-clock per 1,000 postings on the hardware the model ran on; TabPFN's own row is at the top for reference.
| Model | Configs | AUC model / TabPFN | Gap | Verdict | s per 1,000 | $ per 1,000 | Weights |
|---|---|---|---|---|---|---|---|
| TabPFN-3.5, local | 1 | 0.908 | reference | 12 GPU / 37 CPU | 0 | 0.9 GB | |
| Gemma 4 31B (bf16) | 3 | 0.881 / 0.923 | -0.042 | TabPFN | 7,780 | 0 | 63 GB |
| Claude Sonnet 5 | 1 | 0.804 / 0.852 | -0.048 | tie | 9,400 | n/a | hosted |
| GPT-6 Astra | 2 | 0.874 / 0.923 | -0.049 | TabPFN | 705 | 4.22 | hosted |
| Claude Fable 5.1 | 2 | 0.872 / 0.923 | -0.051 | TabPFN | 899 | 6.32 | hosted |
| GPT-6 Luna | 1 | 0.866 / 0.923 | -0.057 | TabPFN | 699 | 0.06 | hosted |
| Qwen 3.8 27B (4-bit) | 1 | 0.864 / 0.923 | -0.059 | TabPFN | 31,283 | 0 | 16 GB |
| Gemma 4 26B (8-bit) | 3 | 0.850 / 0.911 | -0.061 | TabPFN | 560 | 0 | 28 GB |
| Qwen 3.8 27B (MLX 4-bit) | 7 | 0.860 / 0.922 | -0.062 | TabPFN | 3,481 | 0 | 16 GB |
| Gemma 4 26B (bf16) | 6 | 0.854 / 0.922 | -0.069 | TabPFN | 1,186 | 0 | 52 GB |
| Gemma 4 26B (4-bit) | 1 | 0.838 / 0.911 | -0.073 | TabPFN | 452 | 0 | 16 GB |
| Muse Glimmer 30B (4-bit) | 2 | 0.838 / 0.911 | -0.074 | TabPFN | 1,619 | 0 | 19 GB |
| GPT-5.4 nano | 1 | 0.757 / 0.834 | -0.077 | TabPFN | 4,700 | n/a | hosted |
| GPT-5.6 Terra | 1 | 0.745 / 0.843 | -0.097 | TabPFN | 9,000 | 18.84 | hosted |
| GPT-5.4 | 1 | 0.728 / 0.841 | -0.114 | TabPFN | 3,800 | 19.28 | hosted |
| GPT-5.5 | 1 | 0.725 / 0.842 | -0.116 | TabPFN | 6,800 | 44.33 | hosted |
| Claude Haiku 4.5 | 1 | 0.790 / 0.911 | -0.121 | TabPFN | 1,011 | 0.58 | hosted |
| GPT-5.4 mini | 1 | 0.698 / 0.853 | -0.155 | TabPFN | 4,200 | n/a | hosted |
| Claude Opus 5 (list-picker) | 4 | 0.689 / 0.814 | -0.125 | TabPFN | 1,564 | 6.88 | hosted |
| Claude Haiku 5.5 (list-picker) | 9 | 0.667 / 0.798 | -0.131 | TabPFN | 205 | 0.10 | hosted |
| Claude Opus 5.5 (list-picker) | 1 | 0.541 / 0.768 | -0.227 | TabPFN | 967 | 5.76 | hosted |
The list-picker rows are the daily editor arms, which choose a handful of postings from a slate rather than scoring each one; their AUC is a coarse pick-or-not score and understates them. On the fairer per-day replay against those arms TabPFN was ahead on the point estimate in 18 of 27 and clearly ahead in 7. The 120B open-weight model judged too few labeled postings to be included; on the 30 it did, it scored 0.531 and took a day per thousand.
Four things the table says that the headline does not. Price does not buy accuracy here: the cheapest hosted frontier model, GPT-6 Luna at six cents per thousand, lands within a hundredth of Astra at four dollars, and the most expensive per posting, GPT-5.5 at forty-four dollars, is among the worst. Size does not either: the best language model in the table is a local 31-billion-parameter Gemma, free to run, which took over two hours per thousand postings and 63 gigabytes of disk to finish 0.04 behind a model that fits in under one. The configuration matters as much as the model: Qwen 3.8 27B spans 0.717 to 0.864 across its configurations, a wider range than the gap between the best language model and TabPFN, which is the lesson of the previous article in this series restated in one row. And on the company-held-out test the only row TabPFN could not separate from was one Sonnet 5 run; on the forward-in-time split, where TabPFN learns only from older postings, the local Gemma and Qwen models catch up to a tie alongside Astra and Fable. That is the honest limit of the result: a table model with fresh labels beats everything; a table model with stale labels ties the best of the language models, which still cost more and took longer to tie it.
Part of the Product Management series: how AI is changing what product managers actually do.


