The New Architect Role: From Visio Charts to Landscape Experiments
I tested eleven technologies and eight LLMs on one triage problem over a weekend. A logistic regression won. The bigger finding: a test that used to take a quarter now takes a weekend, and that changes what an architect is for, especially where the worst case is a missed diagnosis.

I have been building an agent for a close family member who lost his job to one. Its job is unglamorous: read a few hundred job postings a day, decide which ones deserve a human's eyes, and match the survivors against a file of things he has actually done. Triage and matching. If you have worked in an emergency department, you know the shape of the problem: most of what walks in is not for you, and the cost of the one case you send home wrongly is not symmetric with the cost of the twenty you kept for an hour too long.
The first version used a large language model for everything, because that is what one does in 2026. It took about a week to notice that the model did not behave like anything I had shipped in twenty years of enterprise software. Same posting, same prompt, different answer on Tuesday. A "confidence" of 0.8 that meant nothing when I checked it against my own labels. A beautifully written explanation for why a Production Technician role was a Product role, because both contain the letters p-r-o-d-u-c-t. Deterministic systems fail loudly and in the same place twice. This one failed politely, fluently, and somewhere new each time.
So the question stopped being "how do I prompt this better" and became "should this step be a language model at all". Which is an architecture question, and I am not an architect. I am a product manager who, in this project, holds the title "the Builder" because the coding agent needed someone to blame. There is no architect on the team. There is no team. So I put on the big shoes.
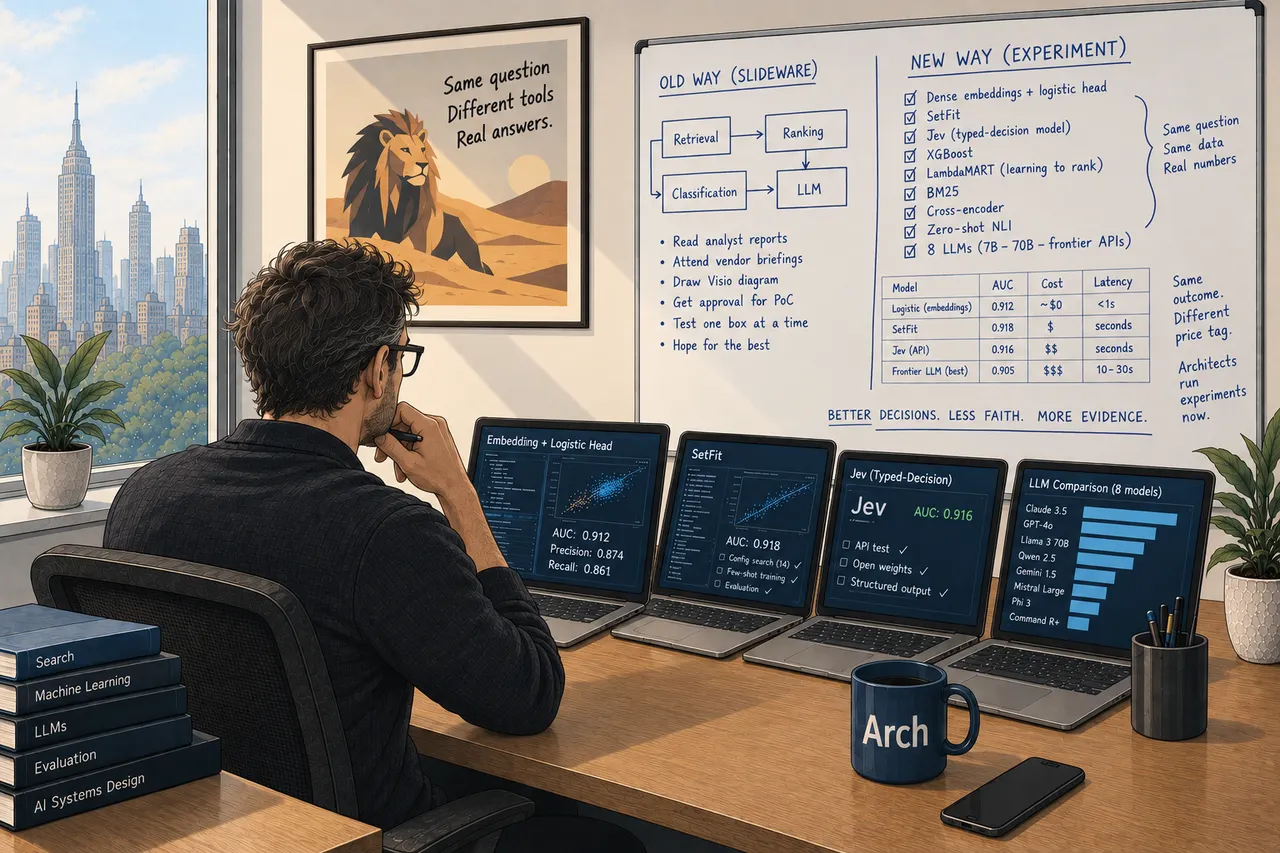
Here is what an architect used to do when facing this question, and I say this with affection, because I have sat in the room. Read the analyst reports. Attend two vendor briefings. Draw a diagram in Visio with boxes labeled Retrieval, Ranking, Classification, LLM, with arrows in tasteful grey. Present it to a steering committee. Get approval for a proof of concept, which would take one sprint per box, which meant one box got tested and the rest were chosen on faith and the quality of the vendor's lunch. The diagram was the deliverable because the evidence was unaffordable.
I did the other thing. Over one weekend, with a coding agent doing the typing and me doing the judging, I tested the landscape. Dense embeddings with a logistic head. SetFit. Jev, a typed-decision model that architecturally cannot write a sentence, in both its open-weight replica and the real API. XGBoost. A real LambdaMART ranker. BM25, the 1994 search algorithm your library catalogue still runs on. A cross-encoder. Zero-shot natural language inference. And eight language models, from a 27B running on my desk to the two most expensive frontier models on the market, each asked the same question about the same three hundred postings, one hundred of which the family member had marked "yes, I would apply" and two hundred "no". All of them were hunting the same lion in the same desert.
The lion was a logistic regression.
Not a metaphor. A logistic head on embeddings the pipeline had already computed for every posting scored 0.912 AUC on the held-out set. SetFit, after a search over fourteen configurations, scored 0.918. The real Jev API scored 0.916. The three are inside the noise of fifteen samples; there is no ranking among them, only a price list. The logistic head costs nothing, trains in under a second, and gives the same answer every time. It won the way a generic drug wins: identical outcome, one tenth the invoice.
Everything below it is where the education was. The best local language model, the one the production scorer runs on, scored 0.882. The 120-billion-parameter one scored 0.816, below BM25 from 1994. Zero-shot NLI, the technique that sounds most like what you want, "does this posting entail a strong fit for this candidate", scored 0.47 to 0.53, which is a coin flip with a GPU bill. The reason is obvious once you see it: the model has no idea who the candidate is. It is answering a different, meaningless question with great fluency, which is, I have come to believe, the defining failure mode of the whole category.
Two technologies I did not test at all, and that was also a result. SPLADE and ColBERT are the current darlings of the retrieval world, and I had a document from a well-meaning source recommending both. But the first stage of my pipeline, plain BM25 with a 99% recall floor, passed 300 of 300 postings. There was no retrieval bottleneck to fix. Retrieval technologies buy you recall over millions of documents. I have thousands, sitting behind a title gate. Testing them would have been testing whether a bigger net catches more fish in a bathtub.
I want to pause on that coin flip, because I kept using clinical words all weekend without noticing. Triage. Matching. At one point, looking at a scorer that listed four pieces of evidence for one requirement, I said "that is not a match, that is a differential", and the coding agent, to its credit, did not ask what I meant. Those are the same words the vendors use in the hospital, for the same operations, with a chart in place of a posting and a protocol in place of a rubric. Matching a job posting to a file of employment history is one thing; the worst outcome is a wasted afternoon. Matching a patient to a diagnosis is another game entirely, played with the same dice, and the dice just lost to a formula from a statistics textbook. Keep that in mind when you read the rest, because the stakes of getting the architecture right scale with the problem, and the method for getting it right does not change.
Two things came out of that weekend, and neither is about job postings.
The first is the argument I have been making in all my books and sessions on AI. Not every problem deserves an agent, and certainly not every problem should be solved with a language model. I used to make that argument with my hands, in a meeting, against a slide that said "AI-first". It never worked, because the slide had a budget and my hands did not. Now I make it with a table. Twelve rows, one per technology, a column for accuracy and a column for cost, and a logistic regression at the top. Nobody argues with the table. They ask for the CSV.
The second is the one I did not expect, and it is the reason for the title. Each of those experiments, done the old way, would have taken me three days to a week: reading the documentation, building a harness, assembling test data by hand, running it, fixing the errors, and learning by trial and error which of the forty configuration knobs matters. Twelve experiments is a calendar quarter of one engineer, or two quarters with the meetings. It took less than a weekend. Call it ten to fifteen times faster; the number is my estimate, not a measurement, and anyone who has run those sprints can supply their own and will land in the same range.
But speed is the boring half of that. The interesting half is what it does to decisions. At three days per option, nobody tests twelve. They test one, the one someone already believes in, and the belief becomes the architecture and the architecture becomes the roadmap and three years later nobody remembers it was a guess. At half a day per option, the honest ranking is affordable, and the null results are what you are paying for. NLI at chance, ColBERT never needed, the 120B model losing to a search algorithm older than the intern: each of those is a decision that, in the old process, would have shipped, because nobody would have had the budget to find out it was wrong. A failed experiment used to be a wasted sprint. Now it is the cheapest thing on the invoice, and it is also the deliverable.
Which brings me to the architect. The role never was about the diagram. The diagram was a compression artifact, a way of communicating a judgment when the judgment could not be shown. The job was always to know which component belongs where and why, and to be right about it more often than the vendor. What changed this weekend is that the judgment can now be exercised on evidence instead of on slideware, by one person, before the steering committee meets rather than after it approves.
That is a promotion, if you take it. The architect who moves from charting to landscape experimentation becomes the most useful person in the building, because they are the only one who can answer "should this be an LLM" with a number. The architect who does not will be replaced, not by an AI, but by a product manager with a coding agent and a free weekend, which is what happened here. I would rather it were the architect. They have the taste for it. I only had the shoes.
And the stakes are the argument for taking it. My weekend was about job postings, where the worst case is a missed interview. The same ladder, rules, then classifiers, then rankers, then generative models, is being climbed right now in places where the worst case is a missed diagnosis, and it is being climbed from the top, because the top rung is the one with the conference talks. A classifier can be enumerated, tested on every case in the validation file, calibrated, and made to say "none of the above". A generative model can do none of that, and it will explain why it did not in beautiful prose, differently on Tuesday. Nobody has to take my word for which rung a given problem belongs on. That is the whole point. Run the table. It takes a weekend now, and the person who runs it, whatever their title, is the architect.
Part of the Product Management series: how AI is changing what product managers actually do.


